Heads of Security: Learned Attention Gates Improve Prompt Injection Robustness
We introduce Heads of Security (HoS), a prompt injection defense that enforces instruction-data separation via a small set of…
AI · Tools · Online creation
Every AI story worth reading, collected hourly from the labs, the tech press, research and the creator economy. Sorted by time, grouped by topic.
3,534 stories · Every headline links to the original publisher. HapnGo curates and groups; we do not copy articles.
We introduce Heads of Security (HoS), a prompt injection defense that enforces instruction-data separation via a small set of…
Relations compose through the entity they share - Alice is Bob's mother and Bob is Carol's father, so Alice is Carol's…
Atmospheric chemical mechanisms are commonly distributed in the language of the Kinetic PreProcessor (KPP), which generates…
Dexterous manipulation with multi-fingered hands is the next frontier of robotics, yet learned hand skills remain limited to…
Scientific discovery often begins with an unexpected observation that prompts a new research question. In a world with altered…
We explore how to build performant large language model (LLM) tool-use agents that complete complex, multi-step tasks…
Weight decay and explicit weight-norm constraints improve optimizer performance in language model pretraining, yet a unified…
Language models pretrained on web corpora collected over multiple years learn both general and domain-specific knowledge. How…
When an LLM group's discussion is compressed into a short memory for a final decision maker, what should the memory keep? Two…
It's a 50 hour course for beginners in AI/ML (obviously it's fully free). Starts out with linear algebra, derivatives, statistics…
AI summary Google Research scientists Ali Behrouz and Vahab Mirrokni, with co-authors, have proposed a framework in which large language models alternate between an active phase and an offline sleep phase. During sleep, the model unlocks extra Mixture-of-Experts memory blocks, moves short-term context into long-term weights, and trains on self-generated "dreams" to sharpen its skills. The team reports near-perfect results on the BABILong benchmark at up to 10M tokens, and almost no loss when learning unseen languages such as Manchu and Kalamang in sequence. On math tests, accuracy reached 79.2% on AIME 24, 69.0% on AIME 25 and 46.1% on HMMT 25, beating SFT, GRPO and other baselines.
In Marvel's VisionQuest, a superpowered robot tries to better understand humanity by getting lost in elaborate, digital daydreams…
AI summary Google Deepmind has unveiled Genie 4, a successor to the Genie 3 model shown in August 2025, which builds interactive worlds frame by frame in real time and now creates its own ambient sound and character speech. Gemini models work behind the scenes, with Gemini 3.8 Flash splitting goals into steps and adjusting plans as the scene or user input changes. The company calls it experimental, noting that details can drift in longer sessions. Only select testers have access for now, with Google AI Ultra subscribers due to follow in the Project Genie web app.
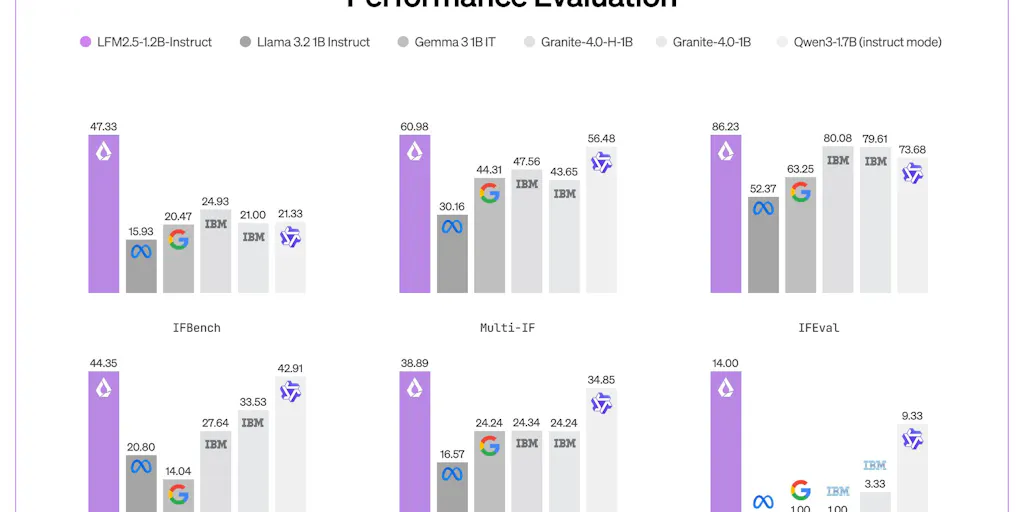
AI summary Liquid AI has launched LFM3, the third generation of its Liquid Foundation Models, starting with six 2B-class open-weight models derived from a shared 1.7B base, covering text, vision, speech, combined omni input and decision tasks. The vision-language model is the first in the family to take video, while the audio model supports speech in 18 languages with first-token latency down to 50 ms. Liquid says the text model needs roughly 1 GB at 4-bit precision, offers a 256K context, and decodes 1.8 to 2.8 times faster on devices than the closest rival it tested. Training used 22T tokens, and the weights are on Hugging Face, with support for Ollama, llama.cpp and other runtimes.
AI summary Liquid has released LFM3, a family of open-weight models of roughly 2B parameters for text, vision, audio, omni and decision tasks, all derived from LFM3-1.7B-Base and each tunable on a single GPU. The base model was pre-trained on 22T tokens, supports a 256K context window, and the 1.7B text model beats LFM2.5-2.6B despite having 35% fewer parameters, scoring 38.42 versus 3.02 on WebArena-Verified. LFM3-VL-2B now accepts video and lifts its average over 62 vision benchmarks to 71.4 from 57.6, while LFM3-Omni-2B is the company's first model combining vision, audio and speech output. The models are available on Hugging Face along with fine-tuning notebooks.
AI summary Google revised its privacy policy, effective October 16, so that content from Gmail, Drive and Google Photos can inform personalized ads when users link those apps to services such as Search or Gemini. The change mainly affects people who opt into Personal Intelligence, and Google has begun testing ads in AI Mode for them. Advertisers get no access to inboxes or photo libraries, no new targeting options and no dedicated reporting, while sensitive categories like health and religion remain excluded. Users can opt out through My Ad Center or by disconnecting the apps in their Google Account settings.
TechCrunch spoke to the MIT computer scientist charged with explaining OpenAI's latest mind-bending discovery.
Better data. Smarter robots. Repeat. Discussion | Link
Seekable OCI (SOCI) indexing for Amazon SageMaker AI training and processing jobs takes full container image download off the…
NVIDIA RTX Spark is a new Windows PC platform for AI development, creation, and gaming in slim laptops and compact desktops…
Property Finder found that 96.8% of their vision-AI evaluation labels were inherited from the incumbent model, hiding its true…
Anthropic wants to have it both ways. With its impending IPO, it wants to tap the vast riches of the public markets and insists…
In this post, we show how Exowatt used Amazon SageMaker AI serverless model customization to build a repeatable AI pipeline that…
Free, daily
One email a day with the AI stories that matter, why they matter, and one tool worth trying. No spam, one-click unsubscribe.