Auto-Research Arena: Benchmarking and Advancing Auto-Research in Language Modeling
As autonomous research systems become more capable, benchmarks must both evaluate their performance and support meaningful…
AI · Tools · Online creation
Every AI story worth reading, collected hourly from the labs, the tech press, research and the creator economy. Sorted by time, grouped by topic.
3,629 stories · Every headline links to the original publisher. HapnGo curates and groups; we do not copy articles.
As autonomous research systems become more capable, benchmarks must both evaluate their performance and support meaningful…
Many everyday tasks require controlling contact force as well as motion. On a humanoid, this force must often be coordinated…
Learning algorithms are usually analyzed under the assumption that informative gradients are continuously available. But this is…
Free, open-source viewer for your own CT, MRI and X-rays Discussion | Link
AI summary AWS has released a refreshed sample showing how to manage computer vision models for each camera across factory fleets with SageMaker Python SDK v3, replacing the deprecated SageMaker Edge Manager with SageMaker Neo. For every camera, a 13-step SageMaker Pipeline trains both an autoencoder that detects anomalies and a ResNet18 classifier for defects, then compiles the approved models with Neo and registers them. To pass quality gates, the anomaly model needs an AUROC of 0.8 or higher, while the classifier must reach 0.6 balanced accuracy and 0.5 defect recall. By default, Step Functions allows up to five runs at once, and a single pass using synthetic data takes roughly $0.07 of compute.
Large language models (LLMs) show promise in specialty medicine, yet existing evaluations largely focus on isolated clinical…
As foundation models evolve from information generation to digital work execution, agents are increasingly capable of completing…
Human oversight is a pillar of AI safety. It is often exercised by a human in the loop (HITL) who approves critical actions taken…
In federated learning (FL), secure aggregation enables a server to compute the sum of local model updates of $N$ clients, without…
Frontier multimodal large language models (MLLMs) can control robots without robot-specific training, but how their capabilities…
AI summary Researchers from the University of Texas at Austin and New York University examined output from 14 language models, including GPT-5.6, Claude and Kimi K2.5, across 980 essays, 45 coding sessions and 120 conversations, comparing it with human writing. They identified six habits that hinder reading, such as rare word pairings, long gaps between linked sentence parts, stacked nouns and nouns used as verbs. The authors point to post-training that rewards correctness in math and code, noting that Llama and the base Olmo model stay closest to human prose. Claude Opus 5.5 outperformed Opus 5 in 19 of 21 comparisons, suggesting targeted finetuning can help.
A vulnerability costs more to fix the later it is discovered. As coding agents generate code faster than developers can review…
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign…
A robot policy needs to understand what a task is asking for in a scene, and how to move the robot to accomplish that task. To…
In comments at a private police conference, Garrett Langley also said his wife advised him to never apologize.
For years I was building WordPress websites and trying to figure out how people were scaling web design agencies to serious…
Prix Pascal de Littérature IA | Dickensian solicitors | Cleobury Mortimer | Great Tapestry of Scotland | From Bayeux to Britain…
A team of AI agents for video: produce, edit, clip, post Discussion | Link
The RealReal, a secondhand luxury fashion consignment retailer, said it's updating its bot defense system, effectively making it…
AI summary Amazon Bedrock can store the processed start of a prompt and reuse it on later requests at a reduced input price, which helps AI agents that resend tools, instructions and history at every step. Developers can let Bedrock pick the cached segment automatically (implicit mode), mark its end themselves with prompt_cache_breakpoint (explicit mode), or combine both; a reusable prefix needs at least 1,024 tokens. In a six-turn test with GPT-6 Astra, implicit caching lowered input cost by about 62% and explicit rolling breakpoints by about 61%.
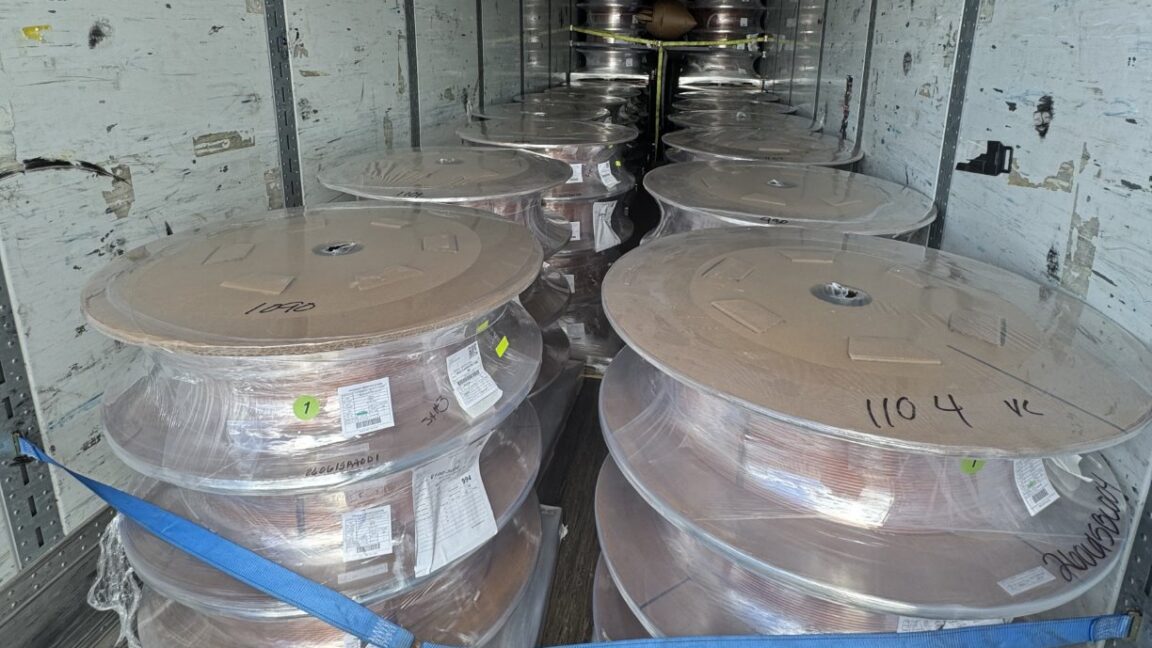
Investigators explain how highway thieves stole $100M in data center equipment.
For the past year I have been studying using a fast K-dim hermite spline manifold algorithm, called K-Splanifolds or KS, for…
AI summary The moderators of Reddit's r/opensource forum announced on Saturday evening that posts about any project using, made with, or aimed at AI are now prohibited. Under the new rules, showcased projects must also be a year old or more, still maintained and backed by several contributors, while posts from non-English speakers will be rejected because moderators cannot distinguish AI-written from translated text. Critics say the policy is overly broad and unclear, noting that the Linux kernel already includes AI-generated code; moderator Wolvereness cited exceptions such as automatic subtitles. A competing subreddit, r/TrueOpenSource, has since launched and permits AI.
Free, daily
One email a day with the AI stories that matter, why they matter, and one tool worth trying. No spam, one-click unsubscribe.